What does a reranker do in a search system?
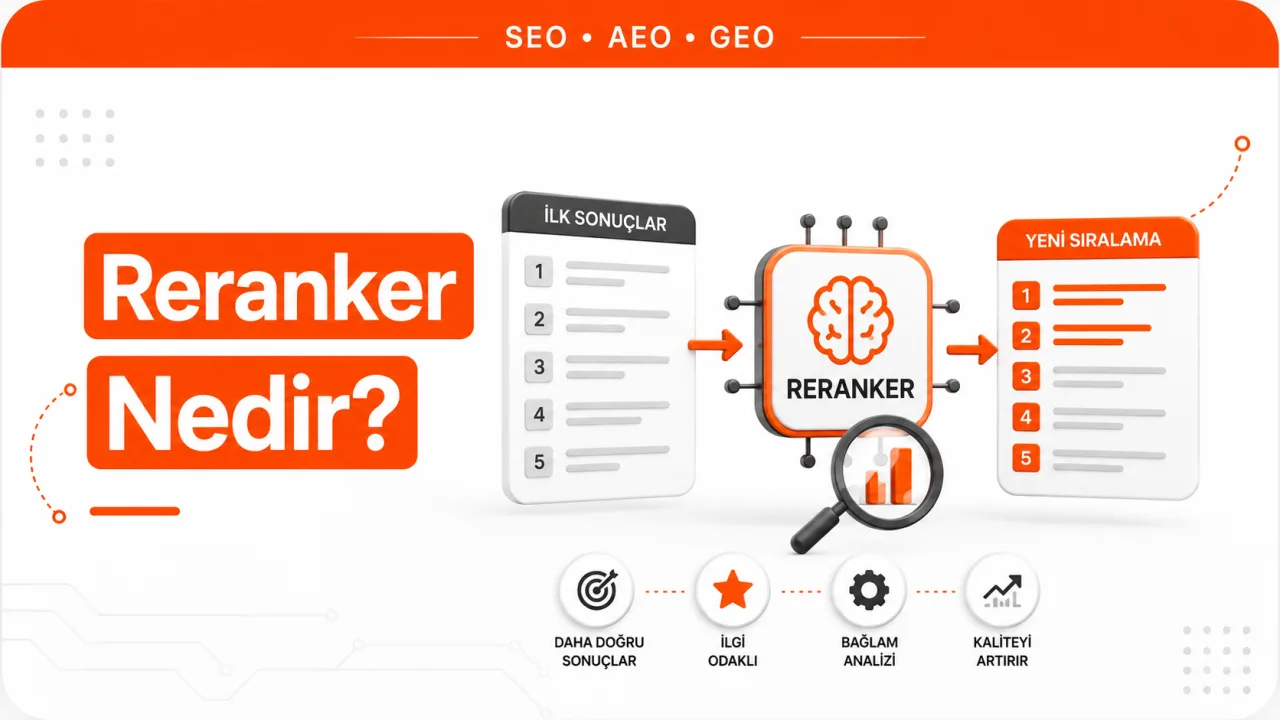
A reranker is the model that rereads each candidate document found in the first retrieval stage of a search or AI answer system alongside the question, and corrects their order. The first stage works fast and coarsely; the second works slowly and carefully. The system spends the expensive careful reading not on millions of documents but only on the shortlist.
The pipeline works like this. A user's question arrives, the first retrieval layer pulls a pool of candidates from the index, the reranker rescores each candidate in that pool by its relevance to the question, and the few highest-scoring passages become the source of the answer. The key limitation of this layer: it can't find a document it isn't given. Microsoft's Azure AI Search documentation states this limitation clearly: the semantic ranker doesn't rerun the query over the entire collection; it only reranks the result set at hand.
That's why reranking sits right in the middle of the citation chain discussed in generative engine optimization. Getting into the candidate pool is one stage, being selected from that pool is a separate stage, and the reasons for failure at each are different.
Why can't every document be read one by one?
The cost of a careful reading model grows with the number of documents. A model that processes the question and the document together has to perform a separate computation for every question and document pair. On an index of hundreds of millions of pages, doing that computation at live query time isn't possible. First-stage retrieval models, by contrast, prepare the document side in advance; when a query arrives they only compare ready-made numbers and return an answer within milliseconds.
How much difference the two-stage setup makes is measurable. On the MS MARCO passage ranking dataset, widely used in the information retrieval literature, a tuned BM25 keyword matching method stays at around 15.3 on the MRR@10 metric, while adding a BERT-based reranker on top of the same BM25 results lifts that value to 35.8. This result belongs to a specific dataset and a specific metric; it isn't a measure of the gain in Google's or any other engine's live system. But it shows well why the reranking layer is considered indispensable.
In the same study, the reranker was given the top thousand passages returned by BM25. The second conclusion drawn from this is more important than the first. If the right passage isn't among those thousand candidates, reranking can't rescue it. The ceiling of the second stage is fixed by the set of documents the first stage captures.
The difference between a bi-encoder and a cross-encoder
A bi-encoder converts the question and the document into sequences of numbers independently of each other. Because document sequences can be computed and indexed in advance, the only work at query time is comparing two sequences. It scales easily, but it can't see subtle relationships between the question and the document, because the model doesn't know what the question is while it processes the document.
A cross-encoder, on the other hand, feeds the question and the passage to the model together as a single text. The model builds connections between the two sides at the word level and produces a single relevance score as output. Because it doesn't produce a separate document vector, it can't be indexed in advance, which makes it impractical for first-stage retrieval but powerful for reranking. The Sentence Transformers documentation ties this distinction directly to a design recommendation: first retrieve around a hundred candidates with a bi-encoder, then have a cross-encoder rescore those candidates.
There are approaches in between as well. The late interaction architecture precomputes the document side at the word level and matches it against query words, striking a balance between the two worlds. A newer pipeline passes the candidate list to a language model all at once and has the model generate the ranking directly. You can find short definitions of these terms together in our AI and SEO glossary.
| Approach | How the question and document are processed | Can the document be precomputed? | Place in the pipeline |
|---|---|---|---|
| Bi-encoder | Converted into number sequences separately, then the sequences are compared | Yes | First-stage retrieval |
| Cross-encoder | Fed together as a single text, producing a single relevance score | No | Reranking |
| Late interaction | The document's word vectors are prepared and matched with query words | Partly | Between the two stages |
| Language model-based list ranker | The candidate list is given to the model all at once, and the model produces the order | No | Reranking |
How much of a page does a reranker read?
Google Search's internal thresholds haven't been disclosed. The technical documentation of products that sell the same architecture, however, is public and shows with concrete numbers how reranking is set up.
- In Azure AI Search's semantic ranker, only the top fifty results from the initial ranking enter reranking. For each document, the model gathers an input of roughly two thousand tokens from the title, keyword and content fields defined in the configuration and produces a relevance score between zero and four.
- In Google Cloud's ranking API, up to a thousand records can be reranked in a single request. The text limit per record is 512 or 1,024 tokens depending on the model, and content exceeding that limit is truncated. Every record must have either a title or content.
The common picture from these two examples corrects the point most often misunderstood on the SEO side. The reranking layer doesn't read the whole page. It reads the limited-length chunk of text it's given, and if that chunk is long, it gets truncated. A perfect answer sitting on the twentieth screen of the page never takes part in scoring if it didn't make it into that chunk.
What is scored at the reranking stage?
The score a reranker produces expresses how well the text it was given answers that question. Its input is the question and the text. The age of the domain, the external link profile or the size of the brand are not among the things this model sees. Those do their work at earlier stages of the pipeline.
Evaluation at the passage level rather than the page level applies in classic search too. Google lists a passage ranking system among its ranking systems and describes it as an AI system it uses to identify individual sections of a page to better understand how relevant the page is to a query. The same logic becomes even more decisive in answer-generating systems, because what enters the model's context isn't the page itself but a chunk cut from it.
The practical conclusion is this. If a section can still be understood when it's pulled out on its own, its chances at the reranking stage are high. A section whose answer leans on the previous section, that doesn't name its topic and that proceeds with vague pronouns looks weak when it's scored on its own.
At what stage do authority signals come into play?
The honest answer to this question has two parts. The provable part is this: Google explicitly lists link analysis systems and PageRank among its ranking systems. So external links are part of the system that determines which pages are brought forward from the index. Google also states that there are no additional requirements for AI Overviews and AI Mode, that these features are built on the existing quality and ranking systems in search, and that they use a query fan-out technique that runs multiple subqueries in parallel.
Where the evidence ends is clear too. Which signal operates at exactly which stage of the pipeline, and with what weight, hasn't been made public. So saying "authority only matters at the first stage" goes beyond the evidence. What can be said is more measured: the input of public reranking products is text, whereas link and brand signals demonstrably play a role in getting a page into the visibility pool.
Most of the published studies on the impact of brand mentions on AI answers are observational and show correlation without establishing causation. So the sound reading is this: link building and passage clarity aren't alternatives to each other. One feeds the chance of the page coming to the table; the other feeds the chance of being picked from the table. A page with strong authority but messy passages gets into the candidate pool and stays there. A page with very clear passages but no visibility at all never even gets scored, because it never enters the pool.
Writing passages that hold up in reranking
The reranking layer isn't under your control, but the text chunk it's given largely is. Here is what works in practice.
- Give the section's answer at the start of the section. The risk of truncation begins at the end of the text, so hiding the real answer at the end can leave it out of scoring.
- Give each section a single informational job. A text that solves two different questions in the same section doesn't look like a clear answer to either.
- Make each section stand on its own. Mention the topic's name at least once within the section, but don't repeat it mechanically at the start of every paragraph.
- Resolve definitions within the section. If a term the reader doesn't know is used, its meaning should be given in the same section.
- Align the heading with the question the section answers. In reranking inputs, the title field usually goes to the model together with the text.
- Don't spread one answer across sections. An answer with half in a table and half three sections away doesn't look complete in any chunk.
These points aren't a new writing technique. A text that is already good in terms of information architecture naturally scores well at the reranking stage too. Understanding reranking shows why this discipline pays off.
Classic ranking and reranking are not the same thing
In classic search engine optimization, the output of ranking is the list the user sees. If you're in third place, you're in third place; that's measurable and reportable. In answer-generating systems, however, the output of reranking is never shown to the user. This ranking is an internal decision about which passages will enter the model's context.
The practical consequence of the difference lies in measurement. A page can be in the candidate pool and never make it into the answer because it couldn't rise to the top in reranking, and from the outside this is indistinguishable from never having been found at all. That's why drawing conclusions about AI visibility from a single attempt at a single query is misleading. Repeating the same question with different wording and at different times is the only way to see the variability in the system's behavior.
Frequently Asked Questions
Is a reranker the same as an embedding model?
No. An embedding model converts text into a sequence of numbers, and these sequences are indexed in advance and used in first-stage retrieval. A reranker takes the question and the text together and produces a single relevance score; it doesn't produce a sequence and can't be indexed in advance. The two work at different stages of the same pipeline.
Does the page title matter in reranking?
In public reranking APIs, the title is part of the record sent to the model. Google Cloud's ranking API requires every record to carry at least a title or content, and Azure AI Search combines the input text from the title, keyword and content fields. So a title that accurately states the section's topic matters not only for readers but for scoring as well.
Is long content a disadvantage in reranking?
Length itself isn't a disadvantage, because the page is already processed by being split into chunks. The problem is when length turns into sprawl within a chunk. A chunk that touches on ten questions at once but answers none clearly scores poorly despite being short. A long text in which every section completes a single job, on the other hand, has an advantage.
Do I need to set up a reranker for my own site?
There's nothing you need to set up to appear in external search and answer engines; that layer is on the engine's side. Things change if you run site search, a help center or a Q&A assistant on your own site. In those systems, adding a reranking layer on top of first-stage retrieval noticeably increases the chance of the right answer coming out on top.