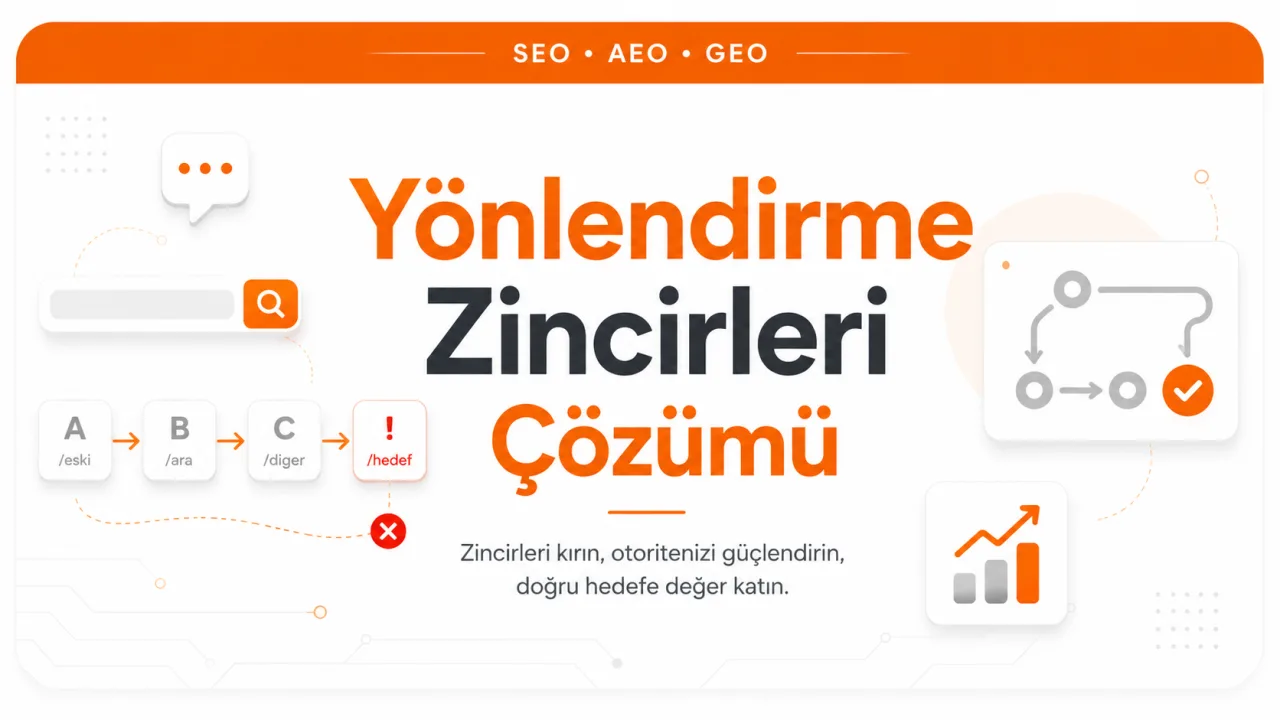
Nobody builds a chain; chains accumulate
Picture a product URL printed in a store's catalog in 2018: http://store.com/product/coffee-grinder. That URL still works today. But the way it works has changed.
In the years since, four separate decisions were made. A certificate was installed and every http request was sent to https. When inconsistent URLs were spotted across the site, the bare domain was pointed to the www version. While simplifying the category structure, the /product/ prefix was dropped. Finally, when the product was merged with another variant, the old slug was redirected to the new one. Four decisions, four rules, four different years.
Someone who looks at the catalog and types that URL into a browser today gets four separate server responses before reaching the content. None of the four rules was wrong; each did the right job on the day it was written. Nobody sat down and built a chain. The chain is the residue left over from correct decisions piling up on top of each other.
The technical definition is simple: a redirect chain is when a URL reaches its final destination not in one step but through one or more intermediate URLs. A client requesting URL A is first sent to B, then to C, and the first byte of content arrives only on the third request. This is also why chains are invisible: the rules don't live on a single screen. One lives in the server configuration, one in the CDN layer, one in a CMS plugin, one in application code. No dashboard shows you all four at once.
A chain and a loop are not the same problem
Both come from the same mechanism, but their consequences are different in kind.
A chain ends. At the end of the sequence there is a URL that returns content, and the page opens, just late. A chain is a performance and maintenance problem.
A loop never closes. URL A sends to B, and B sends back to A. No step returns content. After a certain number of attempts, the browser gives up and shows the user ERR_TOO_MANY_REDIRECTS. The page opens for no one: not for visitors, not for bots. A loop is an accessibility failure.
Loops typically arise from two rules fighting each other. If one layer sends the www version to the bare domain while another layer sends the bare domain to the www version, a loop is inevitable. The same conflict happens on the protocol side: the CDN forces the request to https, and the application behind it thinks the connection is http and redirects it again. Trailing slash rules are another classic source of loops; one rule adds a slash to the end of the URL, another removes it, and the two keep correcting each other forever.
The practical distinction: slowness is a chain, never loading is a loop. A loop needs same-day attention; a chain is planned maintenance.
How far does Googlebot follow a chain?
By default, Google's crawlers follow up to 10 redirect hops. Googlebot generally works with this limit when crawling general web content, but crawlers belonging to different Google products may have different limits. Content fetched from intermediate URLs in the chain is ignored; what gets processed is the content of the final destination URL.
There is a detail most people miss when testing: Google's inspection tools don't follow redirects. So when you give a redirected URL to the URL Inspection tool in Search Console, the tool's behavior is not identical to Googlebot's crawling behavior. If you want to see the end of a chain, don't treat the inspection tool's response as your only evidence.
The type of redirect directly changes the outcome. With a permanent redirect, the new destination is shown in search results, and the redirect is used as a signal that the destination should be the canonical URL; a 301 carries a strong signal in this direction, a 302 a weak one. With a temporary redirect, the source page continues to be shown in search results. When you redirect a URL, Google tracks both the source and the destination; one of them becomes the canonical URL and the other turns into its alternate name. That is why the self-referencing canonical setup on the page at the end of the chain and the redirect rule need to point to the same URL; if they conflict, you are sending Google two signals that cancel each other out. What a permanent redirect carries, and how it is used to recover broken links, is a separate topic covered in detail in our article on broken backlinks and redirects.
Don't read the number 10 as a target; it is a ceiling. An eight-hop chain stays under the limit today, but a single new migration layer pushes it to nine, and the next one to ten. Chains that have crept close to the limit quietly break during the next migration without anyone noticing.
What does a chain really cost?
The most concrete cost is latency, and the reason is simple: hops don't run in parallel, they queue up. The browser can't request the third URL before it learns the second, because it only learns the next stop from the header of the previous response. Each hop is a separate request and response round trip; if the chain jumps to a different domain or subdomain, that round trip may also pay the cost of DNS resolution and establishing a secure connection again. The first byte of content doesn't arrive until the chain ends. On a mobile connection, this is the kind of delay users feel.
The second cost is on the crawling side. Every URL in the chain is a separate request, and none of them returns content. On a small site this is negligible; in a catalog with hundreds of thousands of URLs, every migrated URL carrying two or three hops is a measurable load.
The third cost calls for more careful wording. In SEO circles, percentages circulate along the lines of "this much link equity is lost with each hop." These percentages have no verifiable primary source, and Google doesn't publish a per-hop loss rate. What is documented is simpler and actually harsher: if the limit is exceeded, the destination is never reached, and if one link in the chain breaks, everything behind it breaks along with it. Basing the case for flattening chains on these two definite outcomes, rather than on a disputed percentage, is both more accurate and more useful for making decisions.
How do you find chains?
The "Redirect error" reason in Search Console's page indexing report covers not one situation but four: a redirect chain that is too long, a redirect loop, a redirect URL that exceeds the maximum URL length, and a bad or empty URL in the chain. Read this line not as a warning but as the record of a chain that has already broken. The report doesn't tell you which sub-case applies; you make that distinction by tracing the URL yourself.
The fastest way to see the chain for a single URL is the command line. -I requests headers only, and -L follows redirects to the end:
curl -sIL https://example.com/old-page | grep -iE "^(HTTP|location)"

HTTP/1.1 301 Moved Permanently
location: https://www.example.com/old-page
HTTP/1.1 301 Moved Permanently
location: https://www.example.com/new-page
HTTP/1.1 200 OK
The number of status lines you see in the output is the number of steps in the chain; each location line shows the next stop. This example has two hops, and content arrives at the end. If you forget the -L flag, you only see the first step and miss the rest of the chain entirely. Output where the chain never ends, with the same two URLs going round and round, is the loop itself.
For the whole site, use the redirect report of a crawler tool; there are two things to look for here: chains with more than two steps, and redirected URLs that internal links point to. The second list is usually longer than the first. If you don't run these two crawls on your own site regularly, you can map the URL structure and redirects together as part of an on-page SEO analysis.
Flattening the chain: every old URL straight to the final destination
First, the most common mistake needs to be named, because the number one reason chains grow longer is attempts to fix them. The reflex during a new migration is: "the old rule is already there, let's just add the new one." That doesn't shorten the chain; it adds another link. Adding a rule is not fixing a chain.
The correct order of operations:
- Find the final destination. Follow the chain to the end and identify the URL that returns content. The fix is always written relative to this URL.
- Connect every URL in the chain to that destination individually. For an A → B → C chain, write both an A → C and a B → C rule. The goal is that whichever URL a request arrives at, it ends in a single hop.
- Don't delete the rules for intermediate URLs. Removing B's rule doesn't flatten the chain; it sends external links pointing directly to B and old index entries to a 404. Every URL in the chain stays alive; only its destination changes.
- Check rule order. If more than one pattern in the same file matches the same URL, the server applies the first match. If your new direct rule sits below an old general pattern, it never runs.
- Update internal links. Using redirects within your own site is pure waste, because you already control the destination URL. If the old URL remains in the menu, body text, sitemap or canonical tags, every visit produces an unnecessary hop.
The fifth point is the invisible half of the work. Flattening chains is not just a server rule job; after you fix the rules, as long as the old URL remains on the content side, users and bots keep making the same unnecessary trip.
Set priorities like this: loops first, because the page doesn't open at all there. Then long chains approaching the limit, because they will break on the next migration. Then chains on URLs that receive external links, because there is a real signal to lose there. Internal link cleanup comes last, because its impact is real but no single instance is urgent.
Not creating chains on the second migration
Most chains are born not on the first migration but on the second. That is exactly where prevention belongs.
The basic rule: don't stack rules on a new migration; update the destination of the old rule. If you have a /product/coffee-grinder → /coffee-grinder rule and the product is moving to /burr-coffee-grinder, the right move is not adding a new line but rewriting the first rule as /product/coffee-grinder → /burr-coffee-grinder and adding a /coffee-grinder → /burr-coffee-grinder line next to it. The same job gets done in one hop instead of piling up two layers deep.
The second rule: settle your standards before moving content. Decide the protocol, whether to use www and how to handle trailing slashes once. When these three decisions are made later, each adds a layer to every existing URL, and when all three are delayed, even the shortest path grows to three hops.
The third rule: keep the redirect map. The map is not a working file to throw away when the migration is done; it is the record of the site's URL history. It is the only place where you can update the destinations of old rules during the next migration; without it, everyone goes back to adding new rules.
The fourth rule: measure after the migration. Take a random sample of the migrated URLs and count the hops. Every URL where you see more than one hop tells you the map is incomplete. Running this check the day after the migration is far cheaper than seeing redirect errors in Search Console six months later.
Frequently Asked Questions
Is fixing a two-hop chain urgent?
No, but it should go on the list. Two hops alone are not a crisis; the page opens, Googlebot reaches the destination, and users usually don't notice the difference. The problem is that chains don't shorten on their own. A count of two today becomes three on the next migration and four on the one after that. Fixing two hops is cheap; fixing six is archaeology.
Can't I just delete the old URLs instead of redirecting them?
No. Deleting doesn't end the chain; it ends access. External links pointing to that URL, saved bookmarks, URLs in printed materials and old entries in the index all run into a 404 response. The goal of flattening a chain is not to eliminate intermediate URLs but to make sure all of them reach the final destination in a single step.
What happens if a temporary redirect is left in the middle of a chain?
A temporary redirect doesn't signal that the destination should be the canonical URL, and the source page continues to be shown in search results. A 302 left in the middle of a permanent migration leaves the migration half done from Google's point of view: the URL changed, but nobody said it changed. Use a permanent redirect for every migration you are sure is permanent, and reserve the temporary code for cases that really will be reversed.
Will a chain lower my rankings?
There is no defined penalty for chains, and a chain of reasonable length doesn't mean a ranking loss on its own. The concrete risks are elsewhere: the destination never being reached if the hop limit is exceeded, everything behind a broken link failing at once, and the waiting time each hop adds for users. Fix chains for these three reasons, not because of the loss percentages in circulation.



